

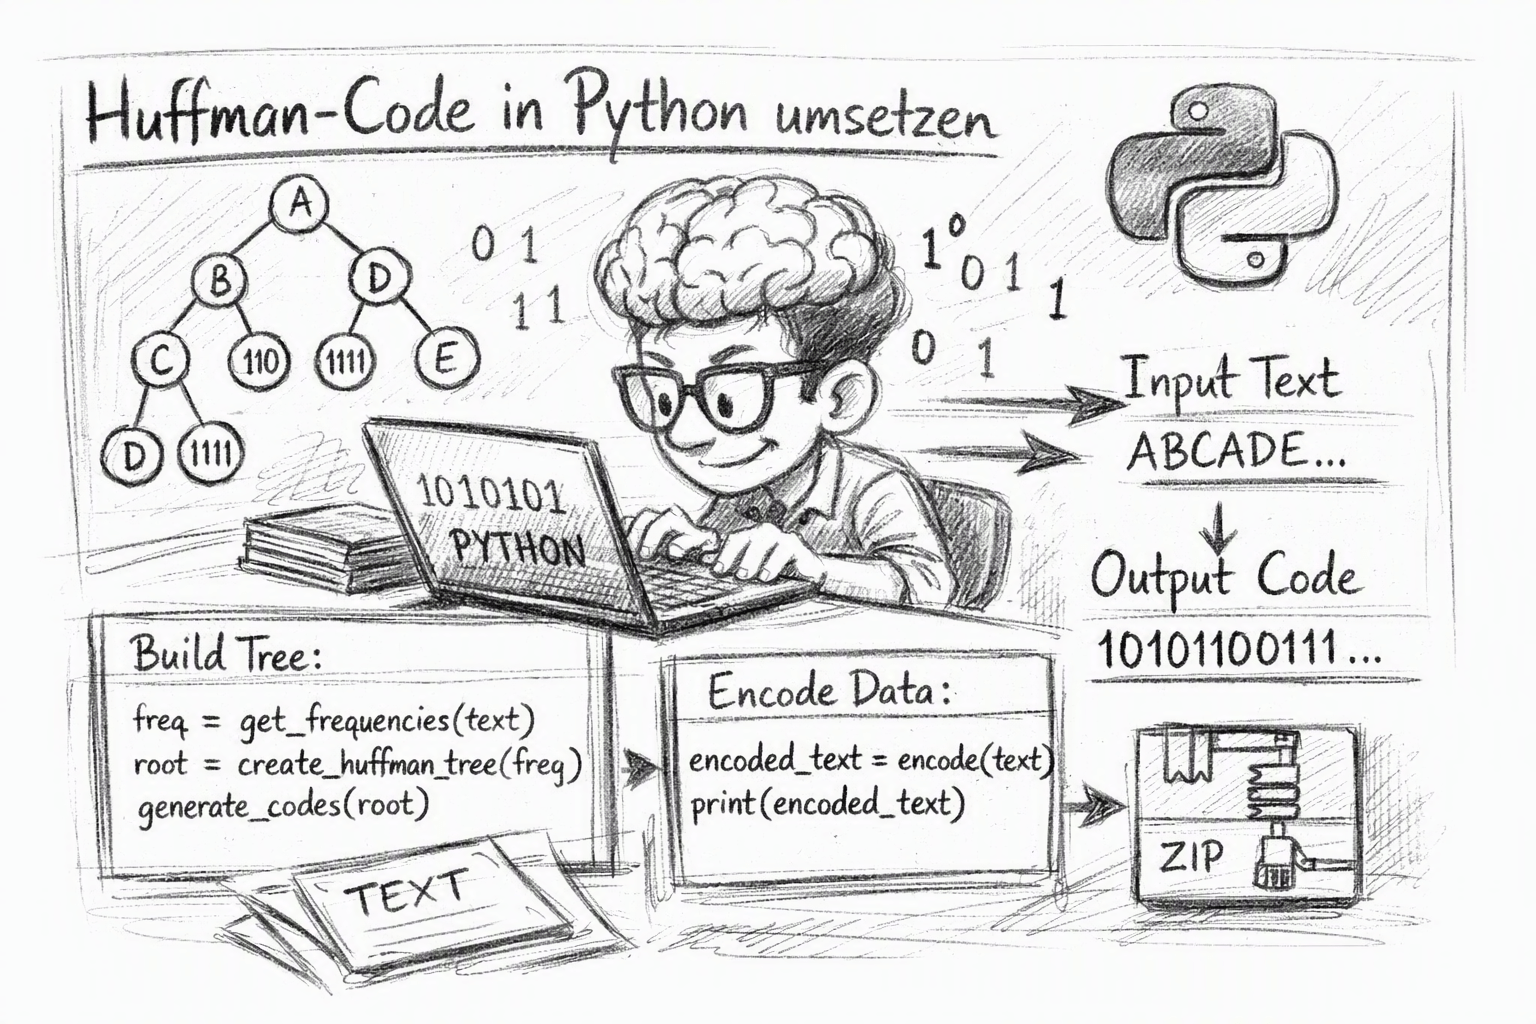
In the first part, the example of KAFFEPAUSE was shown how the Huffman algorithm uses character frequency to create a binary tree and extract space-saving, unique codes from it. The basics are explained in detail in Teil 1 on ffritze.de.
In this second part, the Huffman algorithm is implemented in Python and gradually traced in a Jupyter Notebook. The focus is not only on the finished program. The individual data structures and processing steps are made visible so that the construction of the Huffman tree and the generation of the codes can be tried out directly.
(more…)